Privacy Impact Assessment

Identify, assess, and mitigate privacy risks before they become compliance issues. Auto-generate audit-ready Privacy Impact Assessments (PIA) and Data Protection Impact Assessments (DPIA) pre-populated with the sensitive data flows and privacy risks detected directly in your code.

Closing the Privacy Review to Production Verification Gap

Validate privacy reviews conducted during the design phase with code level evidence during development.

Before Development Begins No Verification
Step 01PIA Request
Step 02Privacy Review
Step 03Development
Verification Gap
Step 05Production

HoundDog.ai closes the gap

  • Verify that code matches the PIA signed off in design
  • Catch log leaks, PII/PHI into unscoped AI, and undocumented third parties before data ever flows

What Is a Privacy Impact Assessment?

A Privacy Impact Assessment (PIA) is a structured process for identifying, evaluating, and mitigating the privacy risks of processing personal data.

A PIA is more than a regulatory requirement. Done well, it shows that an organization understands how personal data is processed, where risks arise, and what controls are in place to reduce harm to individuals.

For regulators, a PIA is evidence of accountability. For organizations, it is a tool that informs design, engineering, and governance.

The challenge is not knowing what a PIA should contain, but having enough visibility, early enough, to describe it accurately. Without a clear view of real data flows, even well-intentioned PIAs quickly become incomplete or misleading.

A defensible PIA must clearly document:

  • What personal data is processed
  • How and why that data is used
  • Where the data flows across systems
  • Which services, APIs, or AI models receive it
  • What safeguards are in place to reduce risk

HoundDog.ai builds Privacy Impact Assessments from actual processing behavior in the codebase, not assumptions, interviews, or outdated architecture diagrams.

Why Traditional PIA Tools Fall Short

Most Privacy Impact Assessments fail for one reason: they are created after systems are designed, integrations are live, and data flows are already in motion.

Manual PIA Workflows Do Not Scale

  • Assessments are completed after architectural decisions are locked in, turning the PIA into a retrospective exercise rather than a meaningful risk control

Paperwork, not a preventive control.

GRC Platforms

  • Provide blank RoPA, PIA, and DPIA templates, like this one from Vanta, and leave privacy teams to interview engineers and collect data flows by hand

Ships the template, not the data flows.

Production-Focused Privacy Tools

  • Infer data flows only after applications are live, missing shadow AI and third-party integrations added directly in code

Reactive detection is no longer enough.

The result

Engineering Fatigue
Questionnaires flood engineering with every release.
Missed AI & Third-Party Flows
DPA violations at best, GDPR fines at worst.
Damage Already Done
Sensitive data leaks into logs and spreads across ingestion systems before anyone is aware.

Typical questions come from different teams

With the self-hosted or cloud platform, your organization’s data map becomes queryable in plain English.

A privacy engineer asks which third-party integrations receive PII.

Which third parties receive PII?

HoundDog.ai Acme Corp
New chat Which third parties receive PII? ···
Ask HoundDog.ai about your data Suggested for you Which repositories handle medical data?Show me the most severe open risky dataflows right nowWhich third parties receive PII?Which AI services receive sensitive data in our code?What data elements are present in my code?
Which third parties receive PII?
Searching…
Searched the datamap
Opened a page
Two third-party data sinks receive PII, counting PHI, PIFI and CHD as PII. Both are in one repository, hounddogai/hounddog-test-python, on the main branch:
Third partyData elementTag and sensitivityDataflows
OpenAI Medical History PHI, high 1 risky dataflow
Sentry Phone Number PII, medium 1 risky dataflow
I've opened the Datamap's Data Sinks view filtered to these two sinks.
Datamap · Data Sinks
Which third parties receive PII? Ask about your data…
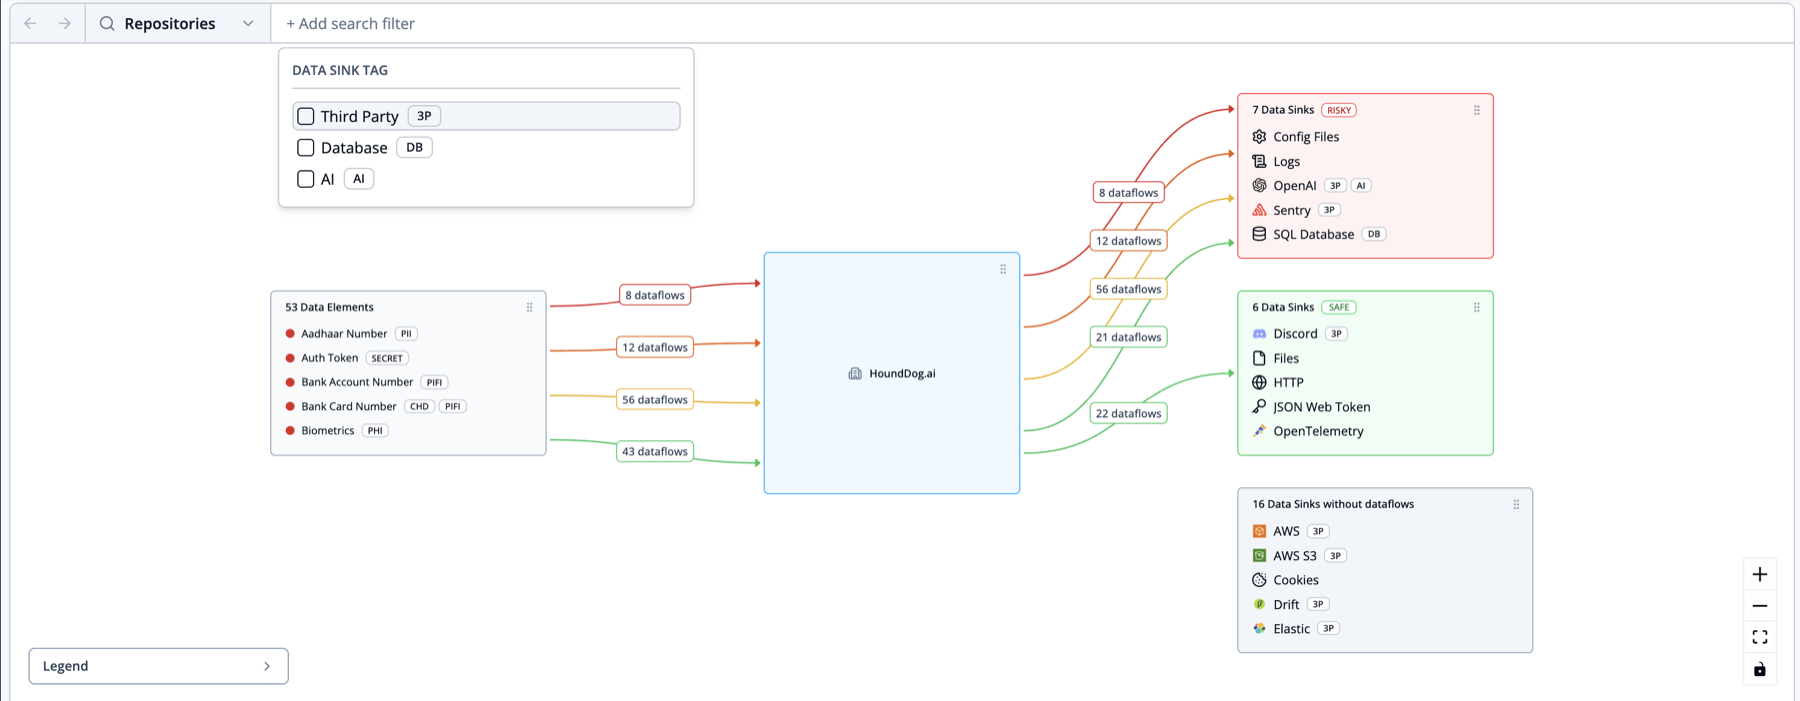
8 dataflows 12 dataflows 56 dataflows 43 dataflows 8 dataflows 12 dataflows 56 dataflows 21 dataflows 22 dataflows
53 Data Elements Aadhaar Number PII Auth Token SECRET Bank Account Number PIFI Bank Card Number CHDPIFI Biometrics PHI
HoundDog.ai
7 Data Sinks RISKY Config Files Logs OpenAI 3PAI Sentry 3P SQL Database DB
6 Data Sinks SAFE Discord 3P Files HTTP JSON Web Token OpenTelemetry
1 dataflow 1 dataflow 1 dataflow 1 dataflow
2 Data Elements Medical History PHI Phone Number PII
HoundDog.ai
OpenAI 3PAI RISKY
Sentry 3P RISKY
Without AI

The same Datamap, built from deterministic findings

Without AI, the Datamap is still available, built from the scanner’s deterministic findings. You can apply the same advanced filters to search for dataflows; there is no chat panel and no AI review.

  • By repository — select several, such as backend, frontend, and an authentication service, to see every dataflow across them.
  • By data element — “show me every repository where Social Security Number is processed” and every sink it may be exposed to.
  • By data sink — “show me all sensitive data sent to OpenAI org-wide.”
The Datamap without AI: 53 data elements flowing through HoundDog.ai into 7 risky data sinks, 6 safe data sinks, and 16 data sinks without dataflows, with the Data Sink Tag filter open

Why not just use an LLM?

HoundDog.ai is built to make your AI more effective, not to replace it.

01

Tokens for reasoning, not discovery.

The scanner discovers every sensitive dataflow, so your AI tokens go to reasoning over detected flows: assessing risk, triaging dataflows and answering questions about your datamap.

02

Evidence you can stand behind.

The same commit always produces the same dataflows. Every engineer, privacy reviewer and agent gets the same answer about where sensitive data goes, instead of output that varies with the prompt.

03

Easy to roll out org-wide.

The Rust scanner runs in CI on standard CPU infrastructure, across every repo and every commit, with negligible impact on build times.

From Documentation Exercise to Preventive Control

Informed by code-level insight, Privacy Impact Assessments stop being a one-time documentation task and become a living control that supports safer system design.

Earlier Risk Identification, Lower Remediation Cost

Privacy risks are surfaced before launch, when fixes require fewer resources and less coordination.

Always-Current Privacy Documentation

Documentation stays aligned as systems, integrations, and logic change: changed data flows become visible, and new integrations are captured.

A Shared Source of Truth

Engineering, privacy, and security teams operate from the same underlying reality rather than conflicting assumptions.

PIAs become a collaborative tool rather than a compliance bottleneck.

Frequently Asked Questions

What is a Privacy Impact Assessment (PIA)?

A Privacy Impact Assessment is a structured process for identifying, evaluating, and mitigating the privacy risks of processing personal data. For regulators, a PIA is evidence of accountability. For organizations, it is a tool that informs design, engineering, and governance.

What is the difference between a PIA and a DPIA?

A Data Protection Impact Assessment (DPIA) is the assessment required under GDPR Article 35 for processing that is likely to result in a high risk to individuals. A Privacy Impact Assessment (PIA) is the broader term used across regulatory frameworks and jurisdictions for the same kind of structured privacy risk analysis. HoundDog.ai pre-populates both PIA and DPIA documentation with the sensitive data flows and privacy risks it detects in code.

How does HoundDog.ai pre-populate Privacy Impact Assessments?

HoundDog.ai analyzes data flows directly inside the codebase, so Privacy Impact Assessments are built from actual processing behavior rather than assumptions, interviews, or outdated architecture diagrams. Detected sensitive data flows and privacy risks pre-populate audit-ready PIA and DPIA documentation aligned with GDPR, CCPA, HIPAA, and other regulatory frameworks, and the documentation stays current as your codebase evolves.

Does this require production access?

No. HoundDog.ai runs entirely in your development environment or CI pipeline, analyzing source code statically. It never needs access to your production database, runtime data, or live systems.

Does it cover AI and LLM data flows?

Yes. HoundDog.ai was built with AI-first workflows in mind. It can detect AI SDKs embedded in your code (LangChain, LlamaIndex, OpenAI, Anthropic, etc.) and trace which sensitive fields flow into LLM prompts, giving you visibility before those calls happen in production so your PIA can assess AI usage accurately.

Make Privacy-by-Design a Reality in Your SDLC

Conduct Privacy Impact Assessments that are grounded in real processing behavior, aligned with modern AI architectures, preventive rather than reactive, and scalable across large applications and teams.